TL;DR
- Problem: Google Sites gives no control over meta tags, canonical, robots.txt, sitemap or structured data, and puts the real content inside sandboxed iframes that many crawlers cannot read cleanly.
- Approach: A Cloudflare Worker sits in front as a reverse proxy. It injects the missing head tags and JSON-LD, serves robots.txt, llms.txt and sitemap.xml, unboxes the iframe for humans, and serves a parity-checked structured ghost payload to AI agents. Search crawlers get the origin HTML plus the same ghost block.
- Result: Crawlers and AI agents get clean, structured HTML instead of an opaque iframe. Lab scores improve, especially on mobile. Current numbers are in Live Telemetry (one PSI run per strategy, homepage only). Cash cost is almost zero.
- Why it matters: Ranking and citation are becoming separate games. If machines cannot read the page cleanly, nothing else matters. High-volume, low-signal content is actively making retrieval worse. Structure and signal density are the real work now.
- Limits: This is a single-site proof of concept under hard constraints. Bot detection is User-Agent based. The ghost payload is still hand-built per page. Lab scores are not field data. No controlled ranking experiment yet. Content quality still decides the outcome.
- Verdict: A working proof that a locked platform can be made machine-readable from the edge alone. Next phase is a proper controlled test and turning the prototype into something that scales. See the Verdict.
- Verify it: open
?debug=bot(AI-agent lane) and?debug=googlebot(search-crawler lane), then compare with the normal page.
Scope of This Proof of Concept
It proves feasibility. On a platform that gives no control over meta tags, canonical, robots.txt, sitemap, heading structure or the iframe sandbox, a structured, verifiable, machine-readable version of the content can be delivered from the edge alone. You can check this with the debug lanes, the validator and the Search Console render comparison.
The question here is machine readability. This work asks whether machines can read the page. The site is indexed and appears for some queries, which I record as an observation: it is one site with no control group, so I don't attribute it to the edge layer. Readability is a precondition for ranking or citation, and measuring the effect is the next phase.
What would test effect. A controlled comparison (matched pages with and without the ghost payload, across several engines and a larger prompt set) is the next phase, and the reason this prototype needs funding to become a product.
Google's own John Mueller called Google Sites "not ideal for SEO purposes" — and he was being generous. Search Engine Journal, 2023. The platform ships with no meta tags, no canonical control, no robots.txt, no sitemap, no structured data, and sandboxed iframes that make Google's own crawler return a blank screen. It is, in practice, close to invisible to crawlers by default.
The control surface is at the network layer. A Cloudflare Worker sits in front, rewrites the response, injects the missing head elements and JSON-LD, serves robots.txt / llms.txt / sitemap.xml, and gives AI agents a parity-checked structured payload while leaving the human interface intact. Lab scores and live telemetry are below. No CMS access was required. This page is the working proof under the constraints I choose.
Why the Edge: 5ms Execution, Not 1-Second Cold Starts
Traditional SEO is brute force; Edge SEO is Leverage. Cloudflare V8 Isolates (the same JavaScript engine as Chrome, running at the CDN edge) execute in milliseconds with zero container cold start. That brief window of Worker CPU time is where I reconstruct the response—deploying an Asymmetric Ghost Payload (AGP) mid-flight to inject high-density semantic nodes and llms.txt schemas. For Generative Engine Optimization (GEO), this architecture is the key: turning a locked-down CMS into a headless engine, and architecting a purpose-built, machine-readable layer strictly for AI crawlers.
The SEO Market Is Shifting. Here Is What That Means For You.
Volume tactics that built search visibility for the last decade are now feeding the exact problem they're trying to solve. High-output, low-signal content doesn't just underperform in AI retrieval — it actively contaminates the retrieval pool. A retrieval system doesn't train on what it fetches, but the rule remains: garbage in, garbage out. If the context window is filled with noise, the engine returns noise. With confidence.
Your ranking didn't change. Your visibility did. Zero-click searches hit 69% in 2025. Only 12% of URLs cited by ChatGPT, Gemini, and Copilot rank in Google's top 10. The overlap varies—Perplexity leans closer to Google's index, while others diverge entirely. But the baseline is clear: you can hold position 1 and be invisible to AI engines. Ranking and citation are increasingly separate games.
The upside is equally real. AI search visitors convert at 23x the rate of traditional organic — they arrive already pre-qualified by the machine. But that traffic only reaches you if the machine can read and trust your page in the first place. Most sites still fail that test. Not a thousand articles. Not another link campaign. A clean, machine-readable entity graph, served straight from the edge, on any CMS.
Every platform has the same ceiling: it cannot control what happens between the request and the response. That gap is where AI crawlers make their citation decision. That gap is where I work.
The Pipeline Is Poisoned: On Signal Quality and Retrieval Collapse
Most SEO is still a volume game. High output, low signal, optimized for ranking systems that no longer fully control what actually gets retrieved. Now the same pattern just comes with newer words — “NLP for SEO”, entity this, AI-ready that — while the underlying practice stays the same.
The damage is structural. RAG systems fetch documents from the live web and generate responses conditioned on what they retrieve. If the retriever surfaces a garbage SEO post, the answer inherits the garbage. At ecosystem scale, researchers call this Retrieval Collapse (Yu et al., 2026, arXiv:2602.16136). The industry built the pipeline, filled it with volume, and now acts surprised at what comes out.
AGP is a working counter-example under hard constraints: one page, locked platform, low-trust domain, parity-checked structured payload from the edge. I am still collecting telemetry on AI-crawler ingestion and RAG citations, so I’m not claiming final results there yet. Hypothesis: structure beats volume, signal beats noise. The machines did not change the rules. They just made low-signal content more expensive to ignore.
Somewhere a content farm is still publishing the 451st generic listicle. The question is whether a clean, machine-readable alternative is easier for retrieval systems to prefer. This page exists so that comparison can actually be made.
What is Edge SEO on a Locked-Down CMS?
The Operator's Definition: System Override
Most people treat Edge SEO as header tweaks at the CDN. That is too small. Here it means full control of the response stream: intercept the request before it reaches the client, neutralize the locked parts of the CMS (no head control, sandboxed iframes, missing robots/sitemap/structured data), and serve the version each audience actually needs. The origin stays untouched.
Serving the Predictive Algorithm
Traditional SEO was engineered for a simpler machine, relying on the sheer volume of content and endless link-building. But the algorithm has matured into a predictive engine that decodes true human intent; it's no longer just counting keywords. You cannot trick a generative AI with outdated tactics. To win in this new reality, you don't manipulate the bot—you serve it perfectly structured context.
The Edge Execution Model
You cannot trick the machine with volume or clever wording. You control the delivery or you lose. Edge SEO takes the CMS out of the decision path. The Worker intercepts the response mid-flight and decides what each type of requester actually receives:
- Humans get the full interface with the iframe unboxed.
- Search crawlers get the origin HTML plus the structured ghost block.
- AI agents get the clean, stripped ghost payload with the same text and facts.
The origin still thinks it served its normal page. The machines get something they can actually parse. Whether they cite it is a separate question — that is what the next phase measures.
[Human UI renders the live ASCII tunnel execution here.]
Code Repository: Review the Worker srcdoc injection and visual override payload on CodePen.
The Real Problem: The Text Exists, the Structure Doesn't
Observed: On Google Sites the content is on the page, but the platform emits it as visually styled blocks with no heading elements. There is no H1, H2 or H3 to set. A machine that reads the page gets text without a document outline: no signal for what the page is about, which parts are subsections, or how they relate.
This is a different problem from "JavaScript content is invisible to crawlers." Googlebot can render JavaScript, and the srcdoc unboxing makes the embedded interface readable. But rendering does not create semantics that were never in the markup. A fully rendered page can still be a flat wall of text.
That gap is what the ghost payload fills. It carries the same content as real semantic HTML: headings in order (H1, H2, H3), JSON-LD describing the entities, and links as readable anchors. Search crawlers receive it prepended to the original page, and AI agents receive it with the origin markup stripped.
Conviction: structure matters for retrieval, not only for ranking. Many retrieval pipelines split documents by headings, and a page with no outline gives them nothing to split on. I treat this as a hypothesis to test, not a result.
Where Google's warning applies, and where it doesn't: Google calls dynamic rendering a workaround for JavaScript-generated content that search engines cannot see. The gap here is structural, not about visibility. On a platform that cannot emit headings and does not allow server-side rendering, the edge is the only layer where structure can be added.
Design direction (proposed, not built): add the structure in place for every visitor. The Worker would turn existing elements into real H1–H3 tags with identical visual styling, so humans and Googlebot receive one DOM and the separate ghost copy shrinks to the AI-agent lane. That would remove the need for a distinct search-crawler lane. Feasibility depends on where the source text lives: in native Google Sites blocks it needs a per-path selector mapping, and in an embed I author the headings can be written directly.
The Core Engine: Asymmetric Ghost Payloads (AGP)
Architecture Overview: The Routing Layer
Control has to start at the routing layer. You do not get authority from inside a locked CMS. You enforce it at the edge, before the origin even responds. The Worker sits in front as a reverse proxy and decides what each type of requester actually receives.
AGP Architecture Diagram — Asymmetric Ghost Payload Routing Flow
An interactive node diagram showing the complete AGP request lifecycle through the Cloudflare Worker engine — how a single request produces asymmetric renderings (human, search crawler, AI agent) of the same content from one URL.
[Human UI renders the interactive 8-node SVG animation and routing sequence here.]
Architecture Visualization: Review the interactive SVG node diagram and Vanilla JS animation source on CodePen.
Beat Sequence: 7 Steps of the AGP Request Lifecycle
-
BEAT 0 — Packet departs · Bot detection fires
A packet travels from the REQUEST node to the CLOUDFLARE WORKER. The moment it hits the edge, the Worker evaluatesisAIBot,isCrawlerBot, andisMobile. Gate state: CLOSED (HOLD label). Active nodes: REQUEST + WORKER. -
BEAT 1 — R2 early exit · Static assets bypass
Fast path: REQUEST → WORKER → R2 BUCKET. If the path is/assets/*, the Worker proxies it from the R2-backed CDN domain; forllms.txtit callsenv.MY_ASSETS.get()on R2 directly. CMS is entirely bypassed. Active nodes: REQUEST + WORKER + R2. -
BEAT 2 — HTML route · Worker fetches CMS
Packet travels REQUEST → WORKER → CMS ORIGIN. Worker firesfetch(request)upstream. Google Sites serves its vanilla response — it has no idea what is about to happen. Gate state: HOLD (PROC label, blinking). Active nodes: REQUEST + WORKER + CMS. -
BEAT 3 — KV read · AI pre-computed state
KV state data travels KV STORE → WORKER. The Worker starts its KV reads before it awaits the CMS response, so they run in parallel with the fetch: aPromise.allreadsLCP_IMAGE_URL,GHOST_CSS,GSTATIC_CSSandCRITICAL_CSSfromAGP_STATE, and bot requests also read the page's ghost HTML fromSEO_PAYLOADS. The ghost HTML is a pre-written KV entry and the cron AI Worker pre-computes the visual state, so no AI runs at request time. Active nodes: REQUEST + WORKER + CMS + KV + AI. -
BEAT 4 — The fork · GATE OPEN
The AGP moment. Gate opens based on earlier bot detection. One packet entered. Different packagings of the same content exit from one URL. Asymmetric output begins. Active nodes: REQUEST + WORKER + CMS. -
BEAT 5A — Human packet → Rich payload
Human payload travels WORKER → FULL UI node via the HTMLRewriter lane. Every font, image, and script served from R2. Return stream "200 OK" appears. Active nodes: REQUEST + WORKER + FULL UI + R2. -
BEAT 5B — Ghost packet → SEO payload from KV
Ghost payload travels WORKER → GHOST node via the ElementSlasher lane. Payload served fromSEO_PAYLOADSKV. ElementSlasher strips the origin markup for AI + social bots only; search crawlers keep the full origin HTML and also get the ghost block. Same text content as the human layer, checkable via?debug=botand?debug=googlebot. CMS never knew. Active nodes: REQUEST + WORKER + GHOST + KV.
Node Definitions — AGP Architecture
8 nodes form the complete AGP routing topology.
- REQUEST NODE — Entry Point
-
Origin of every packet. Two entity sub-icons: YOU (human browser) and BOT (AI crawler). Classification logic: any bot (
isAIBot,isSocialBotorisCrawlerBot) leaves the human lane and gets the ghost block prepended;isAIBotandisSocialBotadditionally have the origin markup stripped, while search crawlers keep the full origin HTML.?debug=botis a deterministic override for the AI-agent lane and?debug=googlebotfor the search-crawler lane. No entity passes unclassified. Label: "User-Agent" - CLOUDFLARE WORKER — The Switch · The Gate
-
Central node. Serverless V8 isolate at the edge. Contains the
isBot?detection logic and a mechanical gate that physically opens on bot classification. Gate states: HOLD → PROC → OPEN. Domain label: "yourdomain.com · low-latency · serverless · V8 isolate" - CMS ORIGIN — Oblivious Infrastructure
- Google Sites origin server. Serves vanilla unoptimized response. Has zero knowledge of the mid-flight interception. Label: "sites.google.com · oblivious · vanilla serve"
- KV STORE — Ghost Origin · State Memory
-
Cloudflare KV namespace. Holds
LCP_IMAGE_URL,GHOST_CSS,SEO_PAYLOADS, andglobal_gsc_stats(live PSI + GSC telemetry). Ghost HTML lives here — never written to CMS. Fast edge reads. Read viaPromise.allin parallel with CMS fetch. Label: "ghost state · low-latency · AGP_STATE · SEO_PAYLOADS" - AI WORKER — Decoupled Cron Compute · The Brain
-
Secondary Cloudflare Worker on Cron schedule. Completely off the request path. Pipeline: Puppeteer renders locked origin → DOM sanitisation → Llama-3-8b-instruct extracts the hero image URL and dominant background color → KV write (
LCP_IMAGE_URL,GHOST_CSS). Pre-computes so the primary Worker has zero AI latency at request time. It does not write the ghost HTML. - FULL UI — Human Reality · Rich Payload
- Human delivery lane output. HTMLRewriter injects canonical + JSON-LD + OG. LCP poster instant (50 KiB). Heavy AVIF post-paint. Scripts sleep until real interaction. gstatic CSS served from an R2-hosted copy (deferred on mobile). R2 serves the assets. Performance: 99/100. Label: "rich · fast · intact · Human payload = rich injected HTML · 0 bloat"
- GHOST — Bot Reality · Payload Born at Edge
- Bot delivery lane output. Ghost HTML is born at the edge — never written in the CMS. H1→H3 hierarchy + JSON-LD @graph. ElementSlasher fires for AI + social bots only — search crawlers keep the full origin HTML and get the same ghost block. Same text content as the human layer by design, checkable via ?debug=bot. Label: "stripped · semantic · Ghost payload = only in EDGE · H1→H3 · JSON-LD @graph"
- R2 BUCKET — cdn.eryc.my.id + env.MY_ASSETS · The Real CDN
-
Cloudflare R2 object storage. Serves the assets Google Sites cannot host:
/assets/*(proxied by the Worker over HTTP from the CDN domain, with optional edge image resizing), fonts (.woff2) and images (.avif, .webp), plus llms.txt and llms-full.txt, which the Worker reads directly withenv.MY_ASSETS.get(). Cache headers on/assets/*:max-age=31536000, immutable. Early exit — never touches CMS origin. Label: "early exit · assets · /assets/* · llms.txt · fonts · images"
REQUEST (Browser or Bot)
        |
        v
[CLOUDFLARE WORKER — V8 Isolate]
        |
   Promise.all()
   /            \
fetch(CMS)    KV: AGP_STATE + SEO_PAYLOADS
        \            /
         [isBot? GATE]
         /            \
        NO              YES
        |                |
        v                v
  HUMAN LANE        BOT LANES
  HTMLRewriter      SEO_PAYLOADS.get(path) → prepend ghost block
  R2 assets         AI/social: ElementSlasher strips origin
  FULL UI           search crawlers: full origin HTML kept
  JSON-LD inject    Ghost HTML H1→H3 + JSON-LD @graph
  98-100/100        similar content, checkable via ?debug=bot / ?debug=googlebot

  [EARLY EXIT — before the gate]
  /assets/* or llms.txt?
        |
        v
  R2 (CDN proxy for /assets/*; env.MY_ASSETS.get() for llms.txt)
  CMS never contacted
Live performance of this architecture: see Live Telemetry below.
The routing layer performs two foundational operations:
- Host Canonicalization (non-www → www): Requests on the non-www hostname are permanently redirected (301) to the canonical www host, with path and query string preserved. The IndexNow key file, the sitemap route and the POST
/mcpendpoint answer before this redirect. This removes canonical fragmentation and consolidates domain authority before the origin is even contacted. - Path Pruning (The /home Override): Google Sites automatically generates a redundant /home endpoint for the index page. This creates unnecessary duplication and dilutes entity focus. The edge worker intercepts this path and forces a permanent 301 redirect to the clean root (/), preserving structural clarity and entity precision.
Once routing is locked and canonical conflicts are neutralized, the engine deploys the Asymmetric Ghost Payload (AGP). AGP is intrinsically asymmetric because it serves one URL in different packagings: human, search crawler and AI agent. The text content is meant to be the same in all of them, and I run a parity check before every KV write (outside the Worker). Known exceptions are listed under Limits.
[Human UI renders the live ASCII gravitational vortex and chromatic glitch logo here.]
Code Repository: Review the ASCII gravitational vortex and Worker srcdoc injection source on CodePen.
- The Human Layer (human visitors): Humans receive a rich, fully interactive interface with the iframe content unboxed into the page via
srcdoc. - The Crawler Layer (search crawlers): Googlebot, Bingbot and similar search crawlers receive the original Google Sites HTML with the head injection and the same ghost text block prepended to the body. Nothing is stripped and the iframe is not unboxed, so the readable text comes from the ghost block.
- The Ghost Layer (AI agents and social bots): GPTBot, ClaudeBot and similar agents receive that same ghost text with the origin markup stripped, a flattened, high-speed semantic version optimized for machine parsing and structural clarity.
Search crawlers are also identified by User-Agent, so this is dynamic rendering, not identical delivery: their markup differs from what humans receive, and the text is intended to be the same. Only AI agents and social bots, which do not render layouts and work within limited context windows, get the origin markup stripped. You can check the AI-agent lane with ?debug=bot, the search-crawler lane with ?debug=googlebot, or any lane with curl -A "Googlebot".
Cloudflare Workers & HTMLRewriter Integration
Execution occurs mid-flight through serverless edge computation. When a request reaches the CDN, a Cloudflare Worker intercepts it before it is delivered downstream. Instead of passing the locked origin response directly to the client, the Worker streams the response through HTMLRewriter. HTMLRewriter parses and mutates the DOM tree in real time with negligible latency overhead. The system intercepts the <head> and <body> streams and performs controlled structural injections during rendering.
Core edge operations include:
- Canonical Consolidation and Domain Authority: A standard Google Site leaks authority back to its native sites.google.com/view/... origin. The edge neutralizes this by injecting absolute canonical tags directly into the <head>, consolidating all entity authority into the custom domain while treating the origin strictly as infrastructure.
- Structured Payload Injection: Missing metadata, structured schemas, and the Ghost CSS layer are appended directly into the DOM stream prior to render.
- Policy Override: Restrictive Content Security Policies (CSPs) that prevent structural augmentation are handled as follows: the
Content-Security-Policyheader is removed from human HTML responses (not from bot-lane responses), and the iframe sandbox is removed only from embeds I author. Both remove protections Google Sites applies by default, which is acceptable only because the embedded content is mine (see the security note below).
Here is the foundational mechanic of that interception:
// ASYMMETRIC GHOST PAYLOAD: Edge Interception & Mutation
export default {
  async fetch(request, env) {
    const url = new URL(request.url);
    const canonicalHost = "www.yourdomain.com";

    // 1. Proxy Routing: Enforce WWW apex dominance and kill /home
    if (url.hostname !== canonicalHost) {
      return Response.redirect(`https://${canonicalHost}${url.pathname}${url.search}`, 301);
    }
    if (url.pathname === "/home" || url.pathname === "/home/") {
      return Response.redirect(`https://${canonicalHost}/${url.search}`, 301);
    }

    // 2. Fetch the locked origin (e.g., Google Sites)
    const response = await fetch(request);

    // 3. Define the Semantic Ghost Payload
    const schemaGraph = {
      "@context": "https://schema.org",
      "@type": "WebSite",
      "name": "Asymmetric Ghost Engine",
      "url": `https://${canonicalHost}`
    };

    // 4. Stream and Mutate via HTMLRewriter
    return new HTMLRewriter()
      .on('head', {
        element(e) {
          // Unbox the origin: Inject structured JSON-LD & Ghost CSS prior to render
          e.append(`<script type="application/ld` + `+json">${JSON.stringify(schemaGraph)}</script>`, { html: true });
          e.append(`<style id="ghost-css">/* High-speed layout instructions */</style>`, { html: true });

          // Inject custom Meta Descriptions and Canonicals natively missing from the CMS
          e.append(`<link rel="canonical" href="https://${canonicalHost}${url.pathname}">`, { html: true });
        }
      })
      .transform(response);
  }
};
Generative Engine Optimization (GEO) Readiness
Let's be honest about where GEO stands right now. There is no GSC equivalent for AI citations. No consensus tooling. No official standard — the term itself was only formally defined in an academic paper in 2023, and as of early 2026, Wikipedia notes no consensus definition exists in academic literature. Even llms.txt is a community proposal, not a ratified standard. Every RAG pipeline ingests differently. Every LLM has its own retrieval logic. The playbook is being written in real time.
This is the environment I'm building for. AGP is not a theory — it is a working implementation of GEO readiness: force the semantic entity graph into the native DOM before any crawler parses it, serve it from the edge, make it hard to miss. No ranking tricks. No keyword stuffing. Just a machine-readable truth, served with zero friction, from the edge.
Search is aggressively transitioning from traditional keyword-matching to predictive entity-resolution. Generative AI models (like Google's AI Overviews, Perplexity, and ChatGPT Search) do not tolerate noise or ambiguity. They demand a singular, machine-readable truth. The AGP architecture is natively GEO-ready because it explicitly dictates the rules of engagement for AI agents:
- The Algorithmic Red Carpet (robots.txt): Google Sites natively lacks a
robots.txtfile, leaving crawler behavior up to chance. My edge worker dynamically generates and serves one, explicitly defining crawl rules and allowing AI agents (such asOAI-SearchBot) to ingest the semantic layer without friction. It also declares aGoogle-Extendedrule, which is a robots.txt token that controls AI use of content, not a crawler. - Structured Entity Injection: Because the edge controls the stream, I can direct AI agents to targeted
llms.txtfiles or inject pristine JSON-LD entity graphs directly into the HTML. I feed the Large Language Model exactly what it needs to reason about the context, cementing the site not just as a search result, but as a primary cited entity.
In May 2026, Google moved an "Agentic Browsing" category into Lighthouse's default config — grading whether a page is ready not just for AI to read, but to act: accessibility tree structure, layout stability, and WebMCP tool registration. WebMCP is a proposed open standard letting a site declare specific actions an agent can call directly — submit a form, start a booking — instead of guessing from a screenshot. It's still experimental, needs a Chrome origin trial, and fails on most sites today. That's the point: the architecture here was built to serve a flattened, machine-readable entity graph before this category existed. Citation was the first problem. Action is the next one. Current state: the Worker exposes an MCP endpoint at /mcp and sends the origin-trial header, but the client-side WebMCP tool registration is switched off in the current build, so I am not claiming a passing agentic-browsing audit yet.
Why Google Sites? The Strategic Crucible
The Architecture of Simplicity
Google Sites is genuinely good at what it was built for: simple, secure, zero-config publishing. The sandboxed iframes are a solid security choice. For anyone who needs real control over meta, canonical, robots, sitemap, headings, or structured data, those same choices become the problem. The question this experiment asks is simple: can you still make the page properly machine-readable when the origin gives you almost nothing?
The Honest Cost of the Stress Test
This was not efficient and I knew it. I spent months on a platform Google itself says is not ideal for SEO, on a low-trust TLD, with zero control over head, robots, sitemap, or structured data. The sandboxed iframe and the locked origin were the real constraints. I did it on purpose.
Most people would just move to a proper framework. That advice is correct for almost every project. It is the wrong test for the question I was asking. If the edge can deliver clean, parity-checked, machine-readable output even under these constraints, then “no CMS access” is a routing problem, not a wall.
The Stress Test: Solving for the .my.id Variable
Operating on a .my.id domain is a deliberate choice. In the SEO world, this TLD starts with zero inherent trust and is frequently disregarded as low-authority or noise by search algorithms. The goal is to eliminate "domain authority" as a variable in the success equation: if visibility and indexation happen here, they can't be credited to a trusted domain. For what this proof of concept tests, whether the platform's content can be made machine-readable, the domain is not a variable that can explain the result. Any visibility or indexation the site gets is recorded as an observation.
A perspective from the search industry.
TECHNICAL PEER FEEDBACK — View original thread on LinkedIn
[Human UI renders the custom interactive LinkedIn feedback module here.]
Frontend Execution: Review the custom feedback UI component and edge injection source on CodePen.
John Mueller
Senior Search Analyst / Search Relations team lead, Google
"Impressive work & fancy write-up. That looks like a lot of tokens :-). You're probably going beyond what's reasonable for a site, but for practicing, that's sometimes ok. It's a lot of moving parts."
Author Reply (Eryc Tri Juni S): "Spot on John Mueller! It's definitely 'overkill' for a normal site. ha-ha. Since I was building on top of a rigid platform like Google Sites, pushing all those moving parts to the Edge was the only way to intercept the render and serve clean data to AI agents. Definitely not a daily production setup, but a really fun experiment to see how AI crawlers interact with stripped-down DOMs. Thanks for the nod on the write-up! It means a lot coming from you."
Etienne COURSIMAULT
Chief Digital Experience Officer @ Michelin
"Interesting approach. It also seems to confirm the rise of Cloudflare Workers (or similar) as a new programmable edge envelope, where an increasing number of processes—especially those meant for agents—can live independently of the underlying application. Potentially even surfacing legacy systems and progressively wrapping and replacing their capabilities, following 'strangler fig' pattern."
Author Reply: "You absolutely nailed it, Etienne COURSIMAULT. The 'strangler fig' pattern is exactly what makes this approach so scalable for legacy environments. By utilizing Cloudflare Workers (specifically the HTMLRewriter API), we essentially create a decoupling layer at the edge. It allows us to serve perfectly structured, deterministic payloads to AI agents and crawlers independently, without having to wait months for IT to update the underlying monolithic CMS."
Simone De Palma
Technical SEO Manager | Data Analyst | BrightonSEO Speaker
"Cool, that's how I'm going to ship schema markup at scale on my website"
Author Reply: "Exactly Simone De Palma. Bypassing the core application to ship structured data at the edge is a massive time-saver. Since you can parse the DOM on the fly, auto-generating exact schemas becomes effortless. Would love to hear how you plan to structure your payloads!"
Jan Caerels
SEO conf. speaker | SEO Specialist at TUI / Freelance SEO Specialist
"Very impressive tbh!"
Author Reply: "Thanks Jan Caerels! Coming from someone dealing with massive enterprise SEO at TUI, that means a lot. Have you guys started exploring edge-level rendering specifically for AI bots on your end yet?"
Jan Caerels replied: "Eryc Tri Juni S We do plenty of things on the edge yes, but with Akamai :-)"
Author Reply: "Jan Caerels Ah, Akamai! That’s proper enterprise-grade edge computing right there, makes total sense for giant like TUI. I went with Cloudflare Workers primarily because their HTMLRewriter API is incredibly agile for guerrilla DOM manipulation on a locked-down platform like Google Sites. And to be completely honest, it's also 100% free for my scale, which is arguably the best feature for a personal experiment! ha-ha. Do you guys utilize Akamai’s EdgeWorkers for actual DOM stripping for bots, or is it heavily focused on dynamic routing and caching?"
Ravinder Chauhan
Google Platinum in Search & Assistant | AVP - Digital Marketing
"Eryc Tri Juni S , you've done good work. You have completed the tiring work, and at the same time, you have set clear goals so that going forward, through this, we can achieve ...."
Author Reply: "Thanks Ravinder Chauhan! To be honest, executing this on a locked-down platform like Google Sites sometimes feels like strapping a jet engine to a bicycle. ha-ha. But the entire experiment was driven by a bigger architectural question: Can the intelligence layer live entirely outside the CMS? We are facing a fundamental dichotomy right now. Humans need heavy visual effects, rich UI, and engaging experiences. AI bots, on the other hand, strictly need a clean, stripped-down structure that instantly converts to text/markdown. By moving the semantic routing and DOM manipulation to the Edge, we don't have to compromise. We let the CMS handle the frontend presentation, while the Edge serves as the intelligence layer for AI agents. Really appreciate your support and insights on this!"
The Engineering Log: Solving for Hard Constraints
I treat Google Sites as a precision case study in constraint-based optimization. My focus is on augmenting its native stability with a high-velocity delivery layer at the Edge. Navigating this environment has provided the architectural discipline needed to address the unique complexities of any modern CMS stack with surgical precision.
The Engineering Log Matrix — Interactive Transformation Diagram
Visualizes the complete AGP architecture: what gets fixed, how much, and how the routing produces those results.
[Human UI renders the interactive SVG DIP IC chip Transform Matrix animation here.]
Matrix Visualization: Review the interactive SVG Transform Matrix and edge interception logic on CodePen.
Diagram 1 — Transform Matrix: PSI Error → Cloudflare Worker Engine → Fixed
Six real PageSpeed Insights (PSI) errors from the Google Sites origin enter the Worker engine. Each is intercepted mid-flight, mutated, and exits as a fixed output. One partial residual remains: 194 KiB unused CSS — an accepted architectural trade-off (the cost of moving the gstatic stylesheet, a 4,050ms render-blocker on the origin, to an R2-hosted copy that is deferred on mobile and loaded synchronously on desktop).
Data source: Google PageSpeed Insights API v5, Lighthouse 12. Last measured:
Mobile PSI Audit Results
| Row | Category | Engine Operation | Before — Origin | After — Edge | Root Cause | Fix Applied at Edge | Status |
|---|---|---|---|---|---|---|---|
| 1 | Render Blocking | STEP 05 // R2 CSS SWAP | ▲ 4,050 ms | ● 0 ms | gstatic stylesheet · Google Font · 190 KiB blocking critical render path | The gstatic stylesheet link is swapped for an R2-hosted copy (/assets/css/gstatic-cache.css): deferred with media="print" onload on mobile, loaded synchronously with fetchpriority=high on desktop. Google Fonts deferred with media="print" onload | FIXED |
| 2 | Image Delivery | STEP 04 // POSTER-THEN-HYDRATE | ▲ 3,653 KiB | ● 50 KiB | div[aria-label="edge-bg-hijack"] — oversized unoptimized background image blocking LCP | 50 KiB AVIF poster served at LCP via HTTP preload; 3.3 MB high-fidelity AVIF loaded async post-interaction via WakeUpScript + requestIdleCallback | FIXED |
| 3 | Total Blocking Time (TBT) | STEP 05 // SCRIPT SLEEP | ▲ High (see live telemetry) | ● Near zero (see live telemetry) | 734 KiB JavaScript · eval() 764ms · blocking main thread during PSI lab test | All scripts mutated to type="edge-delayed-script" mid-flight; hydration fires on the first mousemove, keydown or touch event (not on scroll or wheel) and is skipped for Lighthouse/PSI runs — scripts wait for first interaction | FIXED |
| 4 | Cache TTL / LCP Priority | STEP 07+09 // AGP_STATE | ■ 1d TTL | ● ∞ cache | fetchpriority missing · 1-day TTL · 1,499 KiB unoptimized assets · no preload hint | R2 serves all assets with Cache-Control: max-age=31536000, immutable; LCP_IMAGE_URL from AGP_STATE KV injected as an HTTP Link: preload response header with fetchpriority=high | FIXED |
| 5 | SEO Score | STEP 02+03 // HEAD INJECT | ● 92/100 | ● 100/100 | No meta description · missing canonical · no structured data | Edge injects: meta description, full JSON-LD @graph (Person + WebSite + TechArticle), canonical, robots.txt with AI crawler rules, llms.txt. (The H1–H3 hierarchy is added for bots via SEO_PAYLOADS; Lighthouse's own run is served the human lane and heading structure is not part of the Lighthouse SEO category, so it is not what moves this score.) | FIXED |
| 6 | Accessibility (A11y) | STEP 06+08 // ARIA+CSS | ● 100/100 | ● 100/100 | 5,353 KiB payload · invalid aria-selected on anchor tags · hamburger menu missing aria-label | Script defer reduces payload; img width/height injected; aria-label force-injected into hamburger div[role=button]; aria-selected corrected to aria-current="page" on nav links | Score unchanged (100 → 100); the underlying violations were fixed. Separate residual: 194 KiB unused CSS, the accepted trade-off from Row 1 (R2-hosted gstatic stylesheet). |
Desktop PSI Audit Results
| Row | Category | Before — Origin | After — Edge | Status |
|---|---|---|---|---|
| 1 | Render Blocking | ▲ 1,200 ms | ● R2 copy, loaded synchronously (same edge) | MITIGATED |
| 2 | Image Delivery | ▲ 1,800 KiB | ● 40 KiB | FIXED |
| 3 | Total Blocking Time | ▲ High (see live telemetry) | ● Near zero (see live telemetry) | FIXED |
| 4 | Cache TTL / LCP | ■ 1d TTL | ● ∞ cache | FIXED |
| 5 | SEO Score | ● 92/100 | ● 100/100 | FIXED |
| 6 | Accessibility | ● 95/100 | ● 100/100 | FIXED. Separate residual: 194 KiB unused CSS (see Row 1). |
Live PSI and Search Console readings: see Live Telemetry below (one canonical copy, refreshed weekly).
The Engineering Log: Solving for Hard Constraints
I treat Google Sites as a precision case study in constraint-based optimization. My focus is on augmenting its native stability with a high-velocity delivery layer at the Edge. The engineering log below details the edge-level transformations the Cloudflare Worker applies mid-flight to work around CMS barriers, including what broke along the way.
Production Infrastructure: You can inspect the complete production source directly. Review the complete AGP Cloudflare Worker routing logic, Edge SEO architecture, and JSON-LD injection source code on GitHub.
Implementation Excerpts (from the production Worker)
How the snippets fit together: they are excerpts from one Worker, not standalone files. Build a single HTMLRewriter named rewriter (Step 02), chain every .on() handler onto it, and call .transform(response) once at the end. Handlers that only apply to human visitors are registered inside if (!isBot). Variables such as url, env, response, isBot, isMobile, isPSI, newHeaders, agpLcpUrl, agpGhostCss and agpGstaticReady are defined in Steps 01, 04 and 07 and reused later. Replace yourdomain.com and placeholder values with your own.
Quick Start: A Minimal Worker You Can Paste and Test
A simplified starting point, not the production Worker. It redirects to the canonical host, injects a canonical tag, and prepends a ghost payload from KV for AI-agent User-Agents (or ?debug=bot). It needs one KV binding named SEO_PAYLOADS, with one key per page path (for example / or /about) holding that page's ghost HTML.
Left out on purpose: AI-agent origin stripping (Step 01), JSON-LD (Step 02), iframe unboxing (Step 03), poster-then-hydrate (Step 04), script deferral (Step 05). Each has its own pitfalls, covered below.
Parity rule: the ghost payload must carry the same text as the page humans see. If the two drift apart, this stops being dynamic rendering and becomes cloaking.
export default {
  async fetch(request, env) {
    const url = new URL(request.url);
    const host = "www.yourdomain.com";
    if (url.hostname !== host) {
      return Response.redirect(`https://${host}${url.pathname}${url.search}`, 301);
    }

    const ua = request.headers.get("User-Agent") || "";
    const isBot = /GPTBot|ClaudeBot|PerplexityBot|OAI-SearchBot/i.test(ua)
      || url.searchParams.get("debug") === "bot";

    // Start the KV read before awaiting the origin, so both run in parallel
    const key = url.pathname.replace(/\/$/, "") || "/";
    const payloadPromise = isBot ? env.SEO_PAYLOADS.get(key) : null;

    const response = await fetch(request);
    if (!(response.headers.get("content-type") || "").includes("text/html")) {
      return response;
    }
    const payload = isBot ? await payloadPromise : null;

    const rewriter = new HTMLRewriter()
      .on('link[rel="canonical"]', { element(e) { e.remove(); } })
      .on("head", {
        element(e) {
          e.append(`<link rel="canonical" href="https://${host}${url.pathname}">`, { html: true });
        },
      });
    if (payload) {
      rewriter.on("body", { element(e) { e.prepend(payload, { html: true }); } });
    }

    const out = rewriter.transform(response);
    const headers = new Headers(out.headers);
    headers.append("Vary", "User-Agent");
    return new Response(out.body, { status: out.status, headers });
  },
};
Step 01: Multi-Lane Bot Detection & Ghost Payload Injection (DSR)
Engineering Strategy: Asymmetric Dynamic Site Rendering
Google Sites renders content inside sandboxed iframes, creating a rendering wall for crawlers. The edge Worker classifies each request into a lane: human, search crawler, or AI agent / social bot. For all bot traffic it reads pre-written, path-matched ghost HTML from Cloudflare KV (SEO_PAYLOADS) and prepends it into the <body>. The KV read is started before the origin response is awaited, so the two run in parallel. Search crawlers keep the full origin HTML plus the ghost block; AI agents and social bots also have the origin markup stripped. The ghost text must match the human text (see the Performance Integrity Protocol).
Implementation Snippet:
// --- THE EXECUTIONER CLASS: removes origin elements for AI/social bots only ---
class ElementSlasher {
  element(el) {
    if (el.getAttribute('data-agp-protected') === 'true') return;   // keep header/footer you own
    if (el.tagName === 'script') {
      const type = (el.getAttribute('type') || '').toLowerCase();
      if (type === 'application/ld+json') return;                   // never strip structured data
    }
    el.remove();
  }
}

// --- BOT DETECTION ---
const userAgent = request.headers.get("User-Agent") || "";
const debugLane = url.searchParams.get("debug"); // "bot" = AI-agent lane, "googlebot" = search-crawler lane

const isAIBot = /OAI-SearchBot|ChatGPT-User|GPTBot|ClaudeBot|Claude-User|Claude-SearchBot|Claude-Web|PerplexityBot|Perplexity-User|Google-Agent|GoogleAgent-Search|GoogleOther|Gemini-Deep-Research|anthropic-ai/i.test(userAgent);
const isCrawlerBot = /Googlebot|bingbot|Applebot|Yandexbot/i.test(userAgent) || debugLane === "googlebot";
const isSocialBot = /FacebookBot|Twitterbot|WhatsApp|LinkedInBot|Telegrambot|Discordbot/i.test(userAgent);
const isBot = isAIBot || isCrawlerBot || isSocialBot || debugLane === "bot";

// --- START THE KV READ BEFORE AWAITING THE ORIGIN (runs in parallel) ---
async function readBotPayload(env, url) {
  try {
    if (env && env.SEO_PAYLOADS) {
      const cleanPath = url.pathname.replace(/\/$/, "") || "/";
      return await env.SEO_PAYLOADS.get(cleanPath);
    }
  } catch (error) {
    console.error("KV Fetch Error:", error);
  }
  return null;
}

const botPayloadPromise = isBot ? readBotPayload(env, url) : Promise.resolve(null);
const response = await fetch(request);               // origin fetch runs while KV is being read
// ... (return early if the response is not HTML, then:)
const botPayload = await botPayloadPromise;

// --- EVERY BOT LANE, search crawlers included: prepend the ghost block ---
if (isBot && botPayload) {
  rewriter.on("body", {
    element(el) { el.prepend(botPayload, { html: true }); }
  });
}

// --- AI AGENTS & SOCIAL BOTS ONLY: strip origin markup. Search crawlers are excluded. ---
if (isBot && !isCrawlerBot) {
  rewriter
    .on('script', new ElementSlasher())
    .on('style', new ElementSlasher())
    .on('iframe', new ElementSlasher())
    .on('noscript', new ElementSlasher())
    .on('header', new ElementSlasher())
    .on('footer', new ElementSlasher())
    .on('div[jscontroller]', new ElementSlasher());
}
Step 02: Head Purification & Document Hygiene
Engineering Strategy: Signal-to-Noise Ratio Optimization
To avoid duplicate tag conflicts, the Worker strips the native canonical, description and og:title tags first, then appends one clean metadata block: canonical, description, llms.txt discovery links and a JSON-LD graph. Order matters: remove before inject.
Implementation Snippet:
const domain = "https://www.yourdomain.com";
const canonicalUrl = domain + url.pathname;

// A small, standalone JSON-LD example. Replace the values with your own entities.
const jsonLd = {
  "@context": "https://schema.org",
  "@graph": [
    { "@type": "WebSite", "@id": `${domain}/#website`, "url": domain, "name": "Your Brand" },
    { "@type": "Person",  "@id": `${domain}/#person`,  "name": "Your Name", "url": domain, "sameAs": ["https://www.linkedin.com/in/your-profile"] },
    { "@type": "TechArticle", "headline": "Your page title", "url": canonicalUrl, "author": { "@id": `${domain}/#person` } }
  ]
};
const jsonLdSchema = `<script type="application/ld` + `+json">${JSON.stringify(jsonLd)}</script>`;

const customHeaderContent = `
  <link rel="canonical" href="${canonicalUrl}">
  <meta name="description" content="Your description here.">
  <link rel="alternate" type="text/plain" href="${domain}/llms.txt" title="LLMs.txt">
  <link rel="alternate" type="text/plain" href="${domain}/llms-full.txt" title="LLMs-Full.txt">
  ${jsonLdSchema}
`;

// agpGhostCss comes from KV (Step 07)
let rewriter = new HTMLRewriter()
  .on('link[rel="canonical"]', { element(e) { e.remove(); } })
  .on('meta[name="description"]', { element(e) { e.remove(); } })
  .on('meta[property="og:title"]', { element(e) { e.remove(); } })
  .on("head", {
    element(e) {
      e.append(customHeaderContent, { html: true });
      if (agpGhostCss) {
        e.append(`<style id="agp-skeleton-css">${agpGhostCss}</style>`, { html: true });
      }
    }
  });
Step 03: Iframe Unboxing via srcdoc (Human Lane)
Engineering Strategy: Mid-Flight Sandbox Override
For human visitors, Google Sites embeds the user's UI in a cross-origin sandboxed iframe, which costs an extra request. The Worker reads the embedded payload from the hidden div[data-code], decodes it, and writes it into iframe.YMEQtf as srcdoc, so the interface is inline in the initial HTML.
Security note: removing sandbox (and, in Step 09, the CSP header) removes protections Google Sites applies by default. Only do this for embeds you author yourself. Never unbox third-party content.
Implementation Snippet:
// Human lane only. The data-code div must appear before the iframe in the document.
// How data-code is encoded depends on the platform: inspect the attribute in DevTools
// and write decodeEmbed() to match. It is left as a stub here on purpose.
function decodeEmbed(raw) {
  // e.g. HTML-unescape and/or base64-decode, depending on what you see
  return raw;
}

let currentEmbedCode = null;

if (!isBot) {
  rewriter
    .on("div[data-code]", {
      element(e) {
        currentEmbedCode = decodeEmbed(e.getAttribute("data-code"));
      }
    })
    .on("iframe.YMEQtf", {
      element(e) {
        if (currentEmbedCode) {
          e.removeAttribute("sandbox");
          e.removeAttribute("src");
          e.setAttribute("srcdoc", currentEmbedCode);   // setAttribute escapes quotes for you
          currentEmbedCode = null;
        }
      }
    });
}
Step 04: Progressive LCP Hydration & Asset Transcoding
Engineering Strategy: Poster-Then-Hydrate Pipeline
A 3.3 MB animated AVIF would ruin Largest Contentful Paint, so the Worker serves a 50 KiB static poster first. The poster URL is preloaded with an HTTP Link response header, which the browser sees before it parses the body. After the page loads, a small client script swaps in the heavy animation when the browser is idle.
Disclosure: Lighthouse/PSI runs are identified by User-Agent and get the poster only, with no heavy-asset upgrade. That keeps the lab run stable, but it means lab scores describe that variant, not what a typical visitor eventually sees. Real-user (field) data is the check that matters.
Implementation Snippet:
const isMobile = /Android|webOS|iPhone|iPad|iPod|BlackBerry|IEMobile|Opera Mini/i.test(userAgent);
const isPSI = /Chrome-Lighthouse|PTST/i.test(userAgent);   // lab runs: poster only
const heavyAnimUrl = isMobile ? "/assets/image/homepage-BG-mobile.avif" : "/assets/image/homepage-BG.avif";

// 1. Poster first; heavy asset URL is stored for later (skipped for lab runs)
rewriter.on('div[aria-label="edge-bg-hijack"]', {
  element(e) {
    e.setAttribute("style", "background-position: center center; background-image: url('/assets/image/homepage-BG-split.avif');");
    if (!isPSI) {
      e.setAttribute("data-heavy-bg", heavyAnimUrl);
      e.setAttribute("id", "lcp-heavy-bg");
    }
  }
});

// 2. Preload hint as an HTTP response header (a normal HTTP header, not TCP/TLS)
if (agpLcpUrl) {
  newHeaders.append('Link', `<${agpLcpUrl}>; rel=preload; as=image; fetchpriority=high`);
}

// 3. Client side, appended to <head> with data-edge-ignore so Step 05 does not delay it
const wakeBgScript = `
<script data-edge-ignore="true">
addEventListener('load', () => {
  if (navigator.webdriver || /Lighthouse|PTST/.test(navigator.userAgent)) return;
  const el = document.getElementById('lcp-heavy-bg');
  if (!el || !el.dataset.heavyBg) return;
  const swap = () => {
    const img = new Image();
    img.src = el.dataset.heavyBg;
    img.decode().then(() => requestAnimationFrame(() => {
      el.style.backgroundImage = "url('" + img.src + "')";
    })).catch(() => {});
  };
  setTimeout(() => ('requestIdleCallback' in window ? requestIdleCallback(swap) : swap()), 250);
});
</script>`;
rewriter.on("head", { element(e) { e.append(wakeBgScript, { html: true }); } });
Step 05: Interaction-Triggered Script Hydration (Near-Zero Lab TBT)
Engineering Strategy: Deferred Main-Thread Hydration
Native platform scripts block the main thread during startup. The Worker rewrites each script's type to text/edge-delayed-script, so the browser does not run it. A small wake-up script re-creates them on the first mousemove, keydown or touchstart. This is what brings lab TBT to near zero.
Trade-offs, stated plainly: the work is deferred, not deleted, so it lands on the first interaction. The real check is INP in field data, not the lab TBT. Scroll and wheel are deliberately not triggers: waking on scroll once produced a 2,696 ms INP on real users. Lighthouse/PSI runs and automated browsers never wake the scripts (the same lab-run special case as Step 04).
Implementation Snippet:
// --- EDGE: put native scripts to sleep (human lane only) ---
if (!isBot) {
  rewriter.on('script', {
    element(e) {
      const type = (e.getAttribute('type') || 'text/javascript').toLowerCase();
      if (type === 'application/ld+json') return;      // structured data stays live
      if (e.hasAttribute('data-edge-ignore')) return;  // your own wake-up scripts stay live
      e.setAttribute('data-original-type', type);
      e.setAttribute('type', 'text/edge-delayed-script');
    }
  });
}

// --- CLIENT: minimal wake-up (append to <head> with data-edge-ignore="true") ---
// Production injects scripts one at a time via requestIdleCallback to preserve order and
// spread the cost; this minimal version re-creates them all at once.
let woke = false;
function wake() {
  if (woke) return;
  if (navigator.webdriver || /Lighthouse|PTST/.test(navigator.userAgent)) return; // lab runs stay asleep
  woke = true;
  document.querySelectorAll('script[type="text/edge-delayed-script"]').forEach(s => {
    const n = document.createElement('script');
    [...s.attributes].forEach(a => {
      if (a.name !== 'type' && a.name !== 'data-original-type') n.setAttribute(a.name, a.value);
    });
    n.type = s.getAttribute('data-original-type') || 'text/javascript';
    n.textContent = s.textContent;
    s.replaceWith(n);
  });
}
['mousemove', 'keydown', 'touchstart'].forEach(ev =>
  addEventListener(ev, wake, { once: true, passive: true }));

// --- R2 CSS SWAP: move the render-blocking gstatic stylesheet to your own copy ---
// Prerequisites: /assets/css/gstatic-cache.css already exists in R2, and the AGP_STATE key
// GSTATIC_CSS is set to "ready" once it is uploaded. If not ready, the original link is kept.
// Do NOT fetch() the CSS inside the rewriter and do NOT inline it. Both were tried:
// the fetch blocked HTML streaming (FCP/LCP stuck near 4.1 s on slow 4G), and inlining
// ~198 KB pushed the HTML to ~250 KB before first paint.
if (!isBot) {
  rewriter.on('link[rel="stylesheet"]', {
    element(e) {
      const href = e.getAttribute('href') || "";
      if (!href.includes('www.gstatic.com')) return;
      if (agpGstaticReady !== "ready") return;
      if (isMobile) {
        // mobile: defer so it cannot block first paint
        e.replace(`<link rel="stylesheet" href="/assets/css/gstatic-cache.css" media="print" onload="this.media='all'">`, { html: true });
      } else {
        // desktop: load normally to avoid layout shift
        e.replace(`<link rel="stylesheet" href="/assets/css/gstatic-cache.css" fetchpriority="high">`, { html: true });
      }
    }
  });
}
Step 06: Fluid Responsive Overrides
Engineering Strategy: Network-Level Layout Stabilization
Google Sites applies hardcoded CSS (for example .EmVfjc) that crops background assets unpredictably across viewports. The Worker injects CSS variable overrides and adjusts inline element styles to keep aspect ratios consistent and reduce layout shift (CLS).
Implementation Snippet:
// Anti-flash + native cropping override, appended to <head>
const fluidityCss = `
<style id="edge-anti-flash">
html { background-color: #060522 !important; }
:root {
  --theme-page_background-color: transparent !important;
  --theme-background-color: transparent !important;
}
body { background-color: transparent !important; }
.EmVfjc { opacity: 0 !important; pointer-events: none !important; display: none !important; }
</style>`;
rewriter.on("head", { element(e) { e.append(fluidityCss, { html: true }); } });

// Element-level fixes (human lane)
if (!isBot) {
  rewriter.on('img', {
    element(e) {
      e.removeAttribute("loading");
      e.setAttribute("decoding", "async");
      const ariaLabel = e.getAttribute("aria-label") || "";

      if (ariaLabel.includes("site-logo-hijack")) {
        e.setAttribute("src", "/assets/image/hero.avif");
        e.removeAttribute("srcset");
        e.setAttribute("fetchpriority", "high");
        e.setAttribute("width", "120");
        e.setAttribute("height", "120");
        e.setAttribute("style", "width: auto !important; object-fit: contain;");
      }
    }
  });
}
Step 07: Decoupled Scanner (R2 CSS Baseline & FCP-Timed Critical CSS)
Engineering Strategy: Off-Request-Path Compute
Anything slow or fragile runs in a second Cloudflare Worker on a Cron trigger, never on the request path. It drives headless Puppeteer against the live site and writes the results to KV and R2, and the primary Worker only reads them. The scanner produces three things that matter for performance:
css/gstatic-cache.cssin R2, plus theGSTATIC_CSS = "ready"flag inAGP_STATE. A cleaned copy of the render-blocking Google Sites stylesheet. The primary Worker (Step 05) swaps the original link for this copy, deferred on mobile and synchronous on desktop. The flag is written only after the R2 upload succeeds, and without it the Worker keeps the original link.CRITICAL_CSSinAGP_STATE. The subset of that stylesheet actually used up to First Contentful Paint, injected inline on mobile only so the deferred full stylesheet does not block the first paint. It is stored only if it is between 100 bytes and 50 KB; otherwise the key is set to an empty string and the Worker falls back to the full stylesheet.LCP_IMAGE_URLandGHOST_CSSinAGP_STATE. The preload target for theLinkresponse header (Step 04) and a small anti-flash background rule. Both are fixed values in the current build (see the note below).
The four phases:
- Find the original stylesheet URL. The scanner loads the site with
?debug=bot. The human lane rewrites the gstatic link to the R2 copy, but the bot lane has no stylesheet handler, so the originalgstatic.comURL is still visible. (This is why the R2 swap must stay human-lane only.) - Save a baseline copy to R2. It fetches the stylesheet directly from gstatic, replaces embedded
data:URIs withnoneto shrink it, uploads it to R2, and only then setsGSTATIC_CSS. Even if everything after this step fails, the page has valid CSS. - Extract critical CSS at FCP. It starts a CSS coverage pass, loads the normal page, and stops the coverage the moment
first-contentful-paintfires (with an 8 s safety timeout). This mirrors how Lighthouse measures unused CSS. Stopping a few seconds later let Google Sites fully initialize and marked the whole 1.5 MB stylesheet as used, which was useless. - Write the fixed state values. It writes the hero URL (
/assets/image/hero.avif) and the anti-flash rule to KV.
What the AI step does today: the scanner still sanitizes the DOM and asks a Workers AI model (@cf/zai-org/glm-4.7-flash, falling back to @cf/meta/llama-3.1-8b-instruct-fp8) for a hero image URL and a background color. The current code validates that output but does not use it: the hero URL and background color written to KV are hardcoded. The AI extraction was an earlier approach; fixed values proved more reliable, because an LLM can return a wrong URL, a heavy asset, or a non-color string. The performance gains described above come from the R2 stylesheet and the critical CSS, not from the model.
Known limitations:
- The coverage pass runs in Puppeteer's default desktop-sized viewport, but the critical CSS is injected on mobile only. If above-the-fold rules differ between viewports, mobile can show a layout shift until the full stylesheet loads. Emulating a mobile viewport during the coverage pass is the next improvement.
- Replacing
data:URIs withnoneremoves any font or icon embedded that way. Check the page visually after the scanner changes the stylesheet. - The scanner depends on the primary Worker's bot lane exposing the original stylesheet link. If the Google Sites markup changes, the scanner logs it and leaves the previous state in place.
- All of this improves lab and first-paint metrics. Confirm the effect with field data.
Security note: the scanner's manual fetch trigger launches a browser and an AI call, so it must be protected with a secret stored as a Worker secret (wrangler secret put SCANNER_KEY) and checked in an Authorization header. Never put a secret in the source code or a URL query string, where it ends up in logs and repositories.
Implementation Snippet:
// --- WORKER 2: THE SCANNER (CRON). Condensed from the production code. ---
import puppeteer from "@cloudflare/puppeteer";

async function extractPayload(env) {
  const browser = await puppeteer.launch(env.MYBROWSER);
  try {
    const page = await browser.newPage();

    // 1. Find the ORIGINAL gstatic URL via the bot lane (the human lane rewrites it to R2)
    await page.goto("https://www.yourdomain.com/?debug=bot");
    const gstaticHref = await page.evaluate(() => {
      const link = document.querySelector('link[rel="stylesheet"][href*="gstatic.com"]');
      return link ? link.href : null;
    });
    if (!gstaticHref) { console.log("No gstatic link found: markup may have changed"); return; }

    // 2. Baseline: fetch, shrink, upload to R2, THEN set the ready flag
    const res = await fetch(gstaticHref);
    if (!res.ok) { console.log("gstatic fetch failed:", res.status); return; }
    let css = await res.text();
    css = css.replace(/url\(['"]?data:[^)]+['"]?\)/g, 'none');   // drops embedded fonts/images
    // Recommended sanity check (add this): never overwrite good state with an error page
    // if (css.length < 1000 || !css.includes('{')) return;
    await env.MY_ASSETS.put("css/gstatic-cache.css", css, { httpMetadata: { contentType: "text/css" } });
    await env.AGP_STATE.put("GSTATIC_CSS", "ready");

    // 3. Critical CSS: stop the coverage at FCP, like Lighthouse does
    await page.coverage.startCSSCoverage();
    await page.goto("https://www.yourdomain.com/");
    await page.evaluate(() => new Promise((resolve) => {
      const observer = new PerformanceObserver((list) => {
        if (list.getEntries().find(e => e.name === 'first-contentful-paint')) {
          observer.disconnect();
          resolve();
        }
      });
      observer.observe({ type: 'paint', buffered: true });
      setTimeout(resolve, 8000);                               // safety timeout
    }));
    const coverage = await page.coverage.stopCSSCoverage();

    const entry = coverage.find(e => e.url.includes('gstatic-cache.css') || e.url.includes('gstatic.com'));
    let critical = "";
    if (entry && entry.ranges.length > 0) {
      critical = entry.ranges.map(r => entry.text.slice(r.start, r.end)).join('\n');
    }
    // Inline only if it is small enough; otherwise the Worker uses the full deferred CSS
    await env.AGP_STATE.put("CRITICAL_CSS", (critical.length > 100 && critical.length < 50000) ? critical : "");

    // 4. Fixed values (the AI extraction result is not used in the current build)
    await env.AGP_STATE.put("LCP_IMAGE_URL", "/assets/image/hero.avif");
    await env.AGP_STATE.put("GHOST_CSS",
      "html { background-color: #060522 !important; }");
  } finally {
    await browser.close();
  }
}

export default {
  async scheduled(event, env, ctx) {
    // waitUntil keeps the Worker alive until Puppeteer and the KV/R2 writes finish
    ctx.waitUntil(extractPayload(env).catch(e => console.error("Cron scanner failed:", e)));
  },
  async fetch(request, env) {
    // Secret lives in a Worker secret, never in the source or the URL
    if (request.headers.get("Authorization") !== `Bearer ${env.SCANNER_KEY}`) {
      return new Response("Unauthorized", { status: 401 });
    }
    try {
      await extractPayload(env);
      return new Response("Scanner executed", { status: 200 });
    } catch (e) {
      return new Response("Scanner failed", { status: 500 });
    }
  }
};
Step 08: Real-Time Accessibility (A11y) Remediation
Engineering Strategy: DOM Mutability Edge Overrides
Accessibility violations hardcoded into a closed origin are corrected mid-flight. The Worker replaces invalid aria-selected on navigation links with aria-current, and injects a missing label into the mobile menu button, before the browser parses the document.
Implementation Snippet:
rewriter
  // Correct invalid ARIA attributes on standard hyperlinks
  .on('a[aria-selected]', {
    element(e) {
      e.removeAttribute('aria-selected');
      e.setAttribute('aria-current', 'page');
    }
  })
  // Inject a missing label into the native mobile menu button
  .on('div[role="button"][aria-haspopup="true"]', {
    element(e) {
      if (!e.hasAttribute('aria-label')) {
        e.setAttribute('aria-label', 'Open Navigation Menu');
      }
    }
  });
Step 09: Priority Synchronization & Defensive Execution
Engineering Strategy: Response Headers and Console Hygiene
The Worker sets the preload hint and the AI-discovery link as HTTP Link response headers, so the browser has them before the body streams. Because the HTML differs by User-Agent, every HTML response also carries Vary: User-Agent. The Content-Security-Policy header is removed on the human lane only (it blocks the Step 03 srcdoc embed), and bot lanes keep it. On the client, small guards stop custom scripts from throwing null-reference errors on subpages that lack their target elements.
Implementation Snippet:
// --- HUMAN LANE ---
let newHeaders = new Headers(response.headers);
newHeaders.delete("Content-Length");
newHeaders.delete("Content-Security-Policy");        // human lane only; see the Step 03 security note
newHeaders.append("Vary", "User-Agent");
if (agpLcpUrl) {
  newHeaders.append("Link", `<${agpLcpUrl}>; rel=preload; as=image; fetchpriority=high`);
}
newHeaders.append("Link", `<https://www.yourdomain.com/llms.txt>; rel="alternate"; type="text/markdown"`);
// Optional WebMCP origin trial. The token is bound to your origin and expires; get your own.
// (Client-side tool registration is switched off in the current build.)
newHeaders.set("Origin-Trial", "<WEBMCP_ORIGIN_TRIAL_TOKEN>");

// --- BOT LANES: keep the CSP, still vary on User-Agent ---
// let newHeaders = new Headers(response.headers);
// newHeaders.delete("Content-Length");
// newHeaders.append("Vary", "User-Agent");

// --- CLIENT-SIDE (a proxied script): defensive guard so subpages stay error-free ---
const options = document.querySelectorAll(".option");
if (options.length > 0) {
  let currentIndex = 0;
  options.forEach((option, index) => {
    option.addEventListener("touchstart", () => { currentIndex = index; /* interaction logic */ });
  });
}
Common Mistakes (each one happened on this build)
- Fetching or inlining the gstatic CSS inside HTMLRewriter. The fetch blocked HTML streaming and held FCP/LCP near 4.1 s on slow 4G; inlining about 198 KB pushed the HTML to roughly 250 KB. Use an R2-hosted copy instead (Step 05).
- Waking deferred scripts on scroll or wheel. It caused a 2,696 ms INP on real users. Wake on mousemove, keydown or touchstart only.
- Leaving the scanner's manual trigger unauthenticated. It launches a browser and an LLM call. Require an Authorization header.
- Forgetting
Vary: User-Agenton HTML that differs by lane, which lets caches serve the wrong lane. - Letting the ghost copy drift from the page text. That turns dynamic rendering into cloaking. Check parity before every KV write.
- Forgetting that sleeping scripts need a wake-up script (with
data-edge-ignore), or the site never becomes interactive.
The Performance Integrity Protocol
Note on Architecture vs. Deception: This is a dynamic-rendering pattern at the edge. Google documents dynamic rendering as a workaround, and explicitly permits it when users and crawlers receive similar text content. To stay on the right side of search guidelines and avoid cloaking, the edge router is built around parity of text, checked when I write each KV entry rather than at request time:
- Search-crawler parity (same text, different packaging): Search crawlers (Googlebot, Bingbot) are not stripped. They receive the original Google Sites HTML plus the same ghost text block that AI agents get. They do not receive the human lane's
srcdocunboxing or script deferral, so their markup differs from what humans receive; the text is intended to be the same. - AI Agent Stripping: Only LLM bots and social bots (GPTBot, ClaudeBot, LinkedInBot) have the origin markup stripped by
ElementSlasher, so that only the noise-free ghost payload remains, because LLMs do not render visual layouts and have strict context windows.
The standing obligation: Across all lanes, the text, links and facts must stay the same; only the packaging differs. Nothing is meant to be hidden or swapped for search engines. Known exceptions: live telemetry values exist only in the human layer, where the ghost copy carries static placeholders. You can verify the AI-agent lane by appending ?debug=bot, the search-crawler lane with ?debug=googlebot, or by fetching the page with curl -A "Googlebot". The Worker sets Vary: User-Agent on HTML responses.
The Strategic Conclusion
If a platform crawlers can’t read can be made machine-readable from the network layer, on a TLD the world ignores, then the method doesn’t depend on the platform. Whether it holds at scale is the next test, not a claim I’m making today.
The Proof: You Are Looking At It (Live Demonstration)
>_ AGP-Validator: Real-Time Node Verification
The AGP Validator is a bespoke, client-side diagnostic terminal engineered to verify the integrity of the Asymmetric Ghost Payload (AGP) architecture. While humans see a rich, interactive interface, this tool allows for the immediate inspection of the "Bot Reality" being served to AI agents.
Operator Instructions: Using >_ AGP-Validator
- Initialization: Click anywhere within the terminal container to focus the input line.
- Command Execution:
./validate-seo.sh: The primary diagnostic script. It initiates a live crawler simulation targeting the edge node with a deterministic?debug=botoverride.clear: Resets the console buffer and wipes current diagnostic logs.
- Interface Shortcuts: The terminal supports Tab-completion for available commands and Ghost Suggestions to assist with command syntax.
[Human UI renders the interactive cyberpunk diagnostic terminal and bash simulation here.]
Diagnostic Console: Review the interactive bash simulation and diagnostic terminal execution source on CodePen.
>_ AGP-Validator — Real-Time Edge Node Verification Terminal
A bespoke client-side diagnostic terminal embedded in the live page. It verifies the integrity of the Asymmetric Ghost Payload (AGP) architecture in real time by fetching the bot reality directly and parsing the semantic payload the Worker injects for AI crawlers. It shows the Worker is running in production — not a mock, not a screenshot.
Primary Command: ./validate-seo.sh
The primary diagnostic script. Executes a live crawler simulation against the edge node using a deterministic ?debug=bot override. Forces the Cloudflare
Worker to serve the AI-bot version of the page: the ghost payload, with scripts, styles, header and footer stripped.
Target URL:
https://www.eryc.my.id/case-studies/edge-seo?debug=bot
The ?debug=bot parameter is the Deterministic Debug Override: a hardcoded override in the Cloudflare Worker that sets isBot = true regardless of
User-Agent, forcing the ghost payload branch to execute. This lets any browser inspect the AI-agent version. ?debug=googlebot simulates the search-crawler lane (full origin HTML plus the ghost block), so ?debug=bot shows only the AI-agent lane.
Validation Checks — What Each Result Shows
0x01 — Metadata and Semantic Signal Verification
- [title] — Title tag present
- A passing result shows the page returns a non-empty title tag. The meta description and JSON-LD checks below are what confirm the edge head injection is live.
- [meta] — Meta description injection
- The Worker strips the native Google Sites description and replaces it with a keyword-optimized value. Passing = clean document hygiene applied.
- [h1] — H1 hierarchy added to the page body
- Google Sites renders content inside sandboxed iframes, so native H1 tags are hard for crawlers to read. A passing result shows the Worker added the ghost payload's heading hierarchy to the page body in the AI-agent layer via
element.prepend(botPayload). The iframe itself is not rewritten in that layer. - [schema] — JSON-LD @graph detected on first paint
- The full JSON-LD @graph is injected by the Worker into the
<head>stream before the browser receives the response body. Passing = instant machine-readable entity graph, no JS execution required.
0x02 — Edge Proxy System File Verification
- /robots.txt — 200 | txt/plain | Nb ⬢
- Confirms the edge Worker dynamically generates and serves a robots.txt. Google Sites natively has no robots.txt — any passing result shows the virtual management layer is operational. The file explicitly allows AI agents (
OAI-SearchBot,GPTBot,ClaudeBot,PerplexityBot) and sets aGoogle-Extendedrule (a robots.txt token, not a crawler) and blocks low-value commercial scrapers (PetalBot). Validation criteria: HTTP 200 + content-type containstext/plain+ byte size > 0. - /llms.txt — 200 | txt/plain | Nb ⬢
- Validates the existence of the markdown-based roadmap for Large Language Models. Served from R2 via
env.MY_ASSETS.get(). Provides LLMs with structured context about the site architecture, semantic entity definitions, and GEO-ready instructions. Validation criteria: HTTP 200 + content-typetext/plain+ size > 0. - /sitemap.xml — 200 | app/xml | Nb ⬢
- Ensures the structural sitemap is accessible and correctly formatted. Served by the Worker as a dynamically generated XML document listing all canonical URLs. Google Sites cannot serve a sitemap natively. Validation criteria: HTTP 200 + content-type contains
xml+ size > 0.
Technical Significance — What a Full Pass Shows
A full pass across all 7 checks (4 metadata + 3 proxy files) shows that:
- The Cloudflare Worker is active and intercepting requests
- The head injection pipeline (meta description, JSON-LD) is operational
- The ghost payload (H1–H3 hierarchy, JSON-LD) is present in the page body served to AI bots
- The virtual management layer (robots.txt, llms.txt, sitemap.xml) is serving from the edge
- The ghost version is reachable on demand. These 7 checks do not test content equivalence, so compare the ghost and human versions yourself with
?debug=bot
This works on the custom domain (www.eryc.my.id) and fails on the native Google Sites URL (sites.google.com/view/eryc-tri-juni-s-notes) because the semantic SEO payload is injected exclusively by the edge proxy. This asymmetry is the proof of concept: it shows the edge layer is what supplies the structure. The effect on ranking and citation is what the next phase measures.
Making the Iframe Content Readable
The iframe wall is handled by the lanes described in Technical Mechanism below: humans get the interface inline via srcdoc, while search crawlers and AI agents get the same content as plain HTML in a ghost block (AI agents without the origin markup). In standard terms, this is dynamic rendering: opaque iframe content becomes readable HTML for machine audiences, ready for Retrieval-Augmented Generation (RAG) ingestion.
The Result: Zero-Bloat Execution
Visually, this removes the native Google loading spinner, so first paint comes sooner and the layout shifts less (see live FCP and CLS above), without the performance tax of a hosted CMS runtime.
Reload Comparison — Instant Render (Zero-Bloat)
Side-by-side reload of the same page. Left: native Google Sites domain — the content lives inside a sandboxed iframe, so the browser shows a dark screen and a spinning loader while that iframe’s code loads and executes. Right: custom domain with AGP — the iframe is unboxed mid-flight via srcdoc, so the UI is already present in the initial HTML and paints without the spinner.
What the Comparison Images Show
These are live page reloads in the human lane. They show the removal of the loading state caused by the iframe’s own code.
Before Edge
URL: sites.google.com/view/eryc-tri-juni-s-notes/home
On the native domain the real content is locked inside a sandboxed iframe. On reload the browser must fetch that iframe, wait for its JavaScript, and only then paint the UI. Result: a prolonged dark screen and the spinning circle. That extra round-trip is the loading cost the edge removes.
After Edge
URL: www.eryc.my.id (custom domain with AGP active)
The Worker rewrites the response mid-flight: it extracts the iframe content, removes the sandbox attribute, and injects the content as srcdoc. The UI is therefore part of the initial HTML. No second request, no spinner, first paint arrives earlier and layout shift is smaller.
Visible content once painted includes:
- Digital ERYC logo with "E·R·Y·C" branding
- "EDGE SEO SPECIALIST MALANG" designation
- Interactive prompt: ">_ How can I help?"
- Navigation options: "● Explore services." and "Get in touch..."
- Attribution note: "P.S. THIS SITE: 100% [Google Sites]"
- Value proposition: "I Help Business Fix or Get Noticed @ low-cost"
This is the human lane. Search crawlers and AI agents receive a different packaging of the same text (see Technical Mechanism). For layout-shift, blocking-time and first-paint numbers, see the live readings above.
What "Instant Render (Zero-Bloat)" Means
- Instant Render
- The edge-optimized page reaches First Contentful Paint (FCP) at roughly a second or less in the live readings above. The LCP image is preloaded via an HTTP
Link: preload; fetchpriority=highheader added by the Worker. The browser receives the hint with the response headers, before it parses the body. The goal is no white flash, no spinner, and minimal layout shift (see live CLS). - Zero-Bloat
- Mobile Total Blocking Time is near zero in the live readings above. The Worker defers native platform scripts (
type="edge-delayed-script") until the first mouse movement, key press or touch, so the main thread stays free during the PSI lab window. Human visitors receive this behaviour; Lighthouse/PSI runs never wake the scripts. Trade-off: this is a lab metric, not field data, and 194 KiB of unused CSS remains (the cost of the R2-hosted gstatic stylesheet — see the Transform Matrix).
Technical Mechanism — How the Render Difference Is Produced
- Native path (Before Edge)
- Browser → Google Sites CDN → sandboxed iframe architecture → iframe must load and execute its own code → spinning loader / dark screen until that finishes.
- Human Lane (normal visitors)
- Browser → Cloudflare Worker → fetches Google Sites response → HTMLRewriter targets
div[data-code]→ decodes the embedded page and fills the live telemetry values → targetsiframe.YMEQtf→removeAttribute("sandbox")+removeAttribute("src")→setAttribute("srcdoc", content). The UI is inline in the initial HTML, so no iframe request is required to paint it. - Search Crawler Lane (Googlebot, Bingbot, Applebot, Yandexbot)
- Crawler → Cloudflare Worker → fetches Google Sites response → head injection (canonical, description, Open Graph, JSON-LD) → reads the ghost HTML for that path from KV (
SEO_PAYLOADS) →element.prepend(botPayload)into<body>. Nothing is stripped, the iframe is not unboxed, and scripts are not deferred. The text is intended to match the human lane; the markup differs. Inspect with?debug=googlebotorcurl -A "Googlebot". - AI Agent Lane (GPTBot, ClaudeBot, social bots, etc.)
- LLM crawler → Cloudflare Worker → reads the ghost HTML for that path from KV (
SEO_PAYLOADS) →element.prepend(botPayload)into<body>. Because LLMs do not render visual layouts and operate under strict context windows,ElementSlasherstrips scripts, styles, iframes and UI bloat, leaving only the machine-readable text.
The Edge Override: Mid-Flight Sandbox Override
The AGP architecture works at the network layer: the Cloudflare Worker sits in front of Google Sites as a reverse proxy and rewrites the HTML stream mid-flight, before it reaches the browser. The exact steps are in Technical Mechanism above; the rewrite runs inside the streaming response and adds minimal latency. Security note: removing the iframe sandbox and stripping the Content-Security-Policy header removes protections Google Sites applies by default. It is acceptable here only because the embedded content is authored by the site owner. Never apply this pattern to third-party content.
The Result: Crawler-Readable Content
Crawlers can read headings, JSON-LD and entity text without executing the iframe’s JavaScript (see Technical Mechanism). That makes the page easier to ingest and cite for Generative Engine Optimization (GEO). It does not guarantee indexing or citation.
GSC DOM Render Output — What the Iframe Content Looks Like to Google
Real Google Search Console URL Inspection screenshots. Left: the native Google Sites domain — the renderer is blocked by the sandboxed iframe and sees almost nothing. Right: the custom domain with AGP — the content that was inside the iframe is now present as native DOM nodes that GSC can parse.
The Two GSC DOM Render States
These are the actual Search Console render outputs (not the human-lane reload comparison above). They show whether Google’s renderer can see the content that originally lived inside the sandboxed iframe.
Before Edge — GSC-render-fail.webp
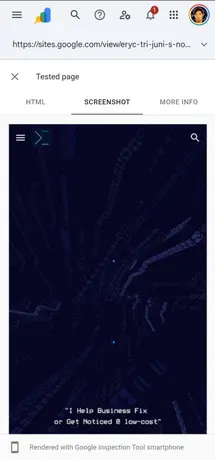
On the native sites.google.com URL the Search Console renderer cannot complete the cross-origin request for the sandboxed iframe (iframe.YMEQtf). It therefore sees no meaningful content — the payload that should be indexed remains invisible.
After Edge — GSC-render-success.webp
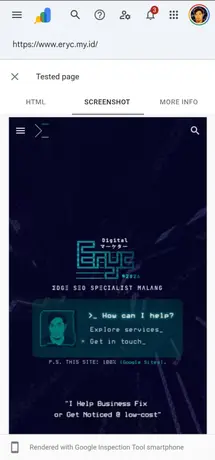
On the custom domain the edge has already made the iframe content available. GSC’s renderer sees the page structure as native nodes — the text, branding and layout that were previously trapped inside the iframe. Note: the URL Inspection fetcher’s User-Agent may receive the human lane (srcdoc unboxing) rather than the search-crawler lane; both lanes carry the same text. The H1→H3 hierarchy and JSON-LD that bots receive come from the ghost block (see Technical Mechanism).
Real-Time Performance Matrix: The Autonomous Feedback Loop
Edge SEO is not merely about payload mitigation; it is an autonomous feedback loop where live telemetry forces semantic adaptation. Here, we break down the exact architecture connecting the edge proxy, the live PSI and GSC API pipeline, and the real-time mutation engine that constantly rewrites the site's JSON-LD structure.
Live Telemetry & API Extraction: The Performance Delta
Standard reporting dashboards typically rely on static historical data or bloated third-party API connectors that actually degrade the Core Web Vitals they are attempting to measure. To prove the continuous efficacy of the Asymmetric Ghost Payload (AGP) architecture without introducing a main-thread rendering penalty, I engineered a lightweight, API-driven telemetry layer using the Google PSI API and GSC API directly. The metrics are injected live into the page via Cloudflare Worker at request time, sourced from the GSC_PSI_EDGE_SEO KV namespace.
<SEO Report>
Live data injected at request time via Google PSI API v5 + GSC API. Updated weekly via Cloudflare Cron.
[Human UI renders the interactive PSI telemetry dashboards (Mobile and Desktop) here.]
Telemetry UI Implementation: Review the Mobile telemetry dashboard frontend UI on CodePen and review the Desktop telemetry dashboard frontend UI on CodePen.
Real-Time PSI Telemetry — Before vs After Edge (Mobile + Desktop)
Two interactive PSI telemetry dashboards showing Lighthouse scores before the edge (Google Sites origin) and after the edge (AGP architecture on www.eryc.my.id). Mobile and Desktop. Both display live data injected at runtime by the Cloudflare Worker from the GSC_PSI_EDGE_SEO KV namespace. Updated weekly via Cron + PSI API v5.
Live Telemetry — Current Readings (Injected at Runtime)
- Desktop PSI — Origin (sites.google.com/view/eryc-tri-juni-s-notes/home)
- Perf: 92/100 | Access: 95/100 | BP: 100/100 | SEO: 92/100 | FCP: 0.9 s | SI: 1.3 s | LCP: 1.0 s | TTI: 2.3 s | TBT: 170 ms | CLS: 0.001 (As of )
- Desktop PSI — Edge (www.eryc.my.id)
- Perf: 98/100 | Access: 100/100 | BP: 100/100 | SEO: 100/100 | FCP: 0.8 s | SI: 1.1 s | LCP: 0.8 s | TTI: 0.8 s | TBT: 0 ms | CLS: 0 (As of )
- Mobile PSI — Origin
- Perf: 55/100 | Access: 100/100 | BP: 100/100 | SEO: 92/100 | FCP: 10.1 s | SI: 10.1 s | LCP: 13.3 s | TTI: 13.3 s | TBT: 100 ms | CLS: 0 (As of )
- Mobile PSI — Edge
- Perf: 99/100 | Access: 100/100 | BP: 100/100 | SEO: 100/100 | FCP: 1.1 s | SI: 2.1 s | LCP: 2.0 s | TTI: 2.0 s | TBT: 20 ms | CLS: 0.045 (As of )
- Google Search Console (last 30 days)
- Clicks: 16 | Impressions: 1620 | CTR: 0.99% | Avg Position: 7.48 (As of )
- Top Search Queries
- edge seo specialist, eryc tri juni s, agp, edge seo indonesia, edge seo specialist malang
- Last verified (weekly cron)
Span format: Perf: {N}/100 | Access: {N}/100 | SEO: {N}/100 | FCP: {v} | SI: {v} | LCP: {v} | TTI: {v} | TBT: {v} ms | CLS: {v}
The live telemetry above lists which audits changed, and every current score is the live reading above, injected from KV at request time (one PSI run per strategy, refreshed weekly). Origin is the Google Sites homepage; Edge is the www.eryc.my.id homepage. PSI scores vary between runs, so read the gap, not a single number.
Lighthouse Threshold Reference — Mobile vs Desktop
| Metric | Mobile — Green (●) | Mobile — Orange (■) | Desktop — Green (●) | Desktop — Orange (■) |
|---|---|---|---|---|
| FCP | ≤ 1.8s | ≤ 3.0s | ≤ 0.9s | ≤ 1.6s |
| SI | ≤ 3.4s | ≤ 5.8s | ≤ 1.3s | ≤ 2.3s |
| LCP | ≤ 2.5s | ≤ 4.0s | ≤ 1.2s | ≤ 2.4s |
| TTI | ≤ 3.8s | ≤ 7.3s | ≤ 2.5s | ≤ 4.5s |
| TBT | ≤ 200ms | ≤ 600ms | ≤ 150ms | ≤ 350ms |
| CLS | ≤ 0.1 | ≤ 0.25 | ≤ 0.1 | ≤ 0.25 |
Score color coding (both): ● green = 90-100 · ■ orange = 50-89 · ▲ red = 0-49.
Analyzing the Score Change: Overcoming Platform Bottlenecks
The live readings above compare the Google Sites origin (sites.google.com/view/...) with the same site served through the edge. The origin ships heavy platform JavaScript and render-blocking CSS, which hurts mobile most. The Worker changes how the page is delivered, and these are the main differences to look for in the readings:
- Render-Blocking Mitigation (LCP): The edge swaps the render-blocking Google stylesheet for an R2-hosted copy (deferred on mobile) and preloads the LCP image, so mobile LCP and FCP should be clearly lower than the origin's. The size of the gap changes between PSI runs.
- Main-Thread Offloading (TBT): Total Blocking Time and the Performance score move the most, because platform scripts are the main source of blocking on the origin. These are lab (Lighthouse) results, not field data.
- Technical SEO Fixes: The origin loses SEO points for missing meta description, heading hierarchy, canonical and structured data. The edge injects all of them. A perfect Lighthouse SEO score is a checklist result, not a ranking guarantee.
This proof of concept (PoC) points to a pattern in the modern, AI-driven web. The underlying CMS you build on matters far less than the network layer that serves it. Crawlers and autonomous LLM engines only index what they are permitted to parse. Ultimately, whoever controls the doorways—the Edge—shapes what machines read.
Indexation Evidence: A Baseline Parsing Test
Google Sites puts the real content inside a sandboxed iframe. A lot of AI crawlers never see it cleanly, and even Google often treats iframe content as belonging to the frame URL, not the parent page. The edge layer turns that content into plain, structured HTML.
The rule is simple: same text, same facts, same links for every lane. Only the packaging changes. That is how you stay on the right side of dynamic rendering instead of sliding into cloaking.
- Layer 1: Human visitors. Full interactive UI, iframe unboxed via
srcdoc, scripts delayed until real interaction. - Layer 2: Search crawlers (Googlebot, Bingbot, etc.). Origin HTML plus the same ghost text block prepended. Nothing stripped.
- Layer 3: AI agents and social bots. Clean, stripped ghost payload only — same text and facts, no origin bloat.
You can check the AI-agent lane with ?debug=bot and the search-crawler lane with ?debug=googlebot. Note: the URL Inspection fetcher’s User-Agent may receive the human layer instead — see the GSC Render Comparison.
What the data shows
Search Console shows impressions for queries matching this content:
- Commercial:
advance technical seo indonesia,edge seo specialist indonesia,geo specialist malang,edge seo malang - Architecture and brand:
asymmetric ghost payload,eryc seo,eryc agp
Ranking for low-competition or coined terms is not a ranking claim. The useful signal is indexation: the text is now readable at all. On the native Google Sites URL the same content sits behind the iframe wall. Side-by-side URL Inspection is a cleaner test than raw search visibility:
- Edge layer off: Render blocked by iframe sandbox (Oct 2026)
- Edge layer on: Full HTML structure and JSON-LD parsed natively (Oct 2026)
Working hypothesis: signal density over volume
This site has only a handful of pages. The hypothesis is simple: a clean, structured, noise-free entity graph served as readable HTML can be understood without hundreds of supporting pages. One site, one test. Treat it as a hypothesis to be replicated, not a final conclusion.
Verdict: A Working Proof of Concept
This experiment was built to answer one question: can a platform that crawlers cannot read be made machine-readable from the network layer alone? Here is what the result shows, in order, including where it stops.
1. Machine Readability Comes First
Conviction: Machine readability comes first. If the page cannot be cleanly parsed, nothing else matters — not content quality, not links, not brand. Ranking and citation both require the content to be readable in the first place. The edge approach does not wait for the crawler to struggle with iframes or missing structure. It supplies a clean, structured version at the network layer. That is the minimum requirement. Everything else is secondary.
Observed: The gap is observable. Both the native Google Sites URL and the edge domain are tracked in Search Console, so the difference can be inspected side by side (see the GSC render comparisons above). The edge layer is a per-page function, so a larger site changes how many times it runs, not what it does.
2. The Constraint Stack
The experiment was deliberately run under the hardest combination of conditions I could find, all at once:
- Platform: Google Sites, which offers no control over meta tags, canonicals, robots.txt, sitemap or structured data. The edge layer adds that whole control surface (robots.txt, sitemap.xml, llms.txt, canonical, JSON-LD) without touching the CMS.
- Experience: a fully interactive interface with an animated background, not a stripped-down page.
- Performance: a PSI score of 99 (lab data, not field data; current numbers are in Live Telemetry).
- Domain: .my.id, a TLD that starts with no inherited trust.
- Infrastructure: hosted on Google's infrastructure and fronted by Cloudflare's (TLS, DDoS protection, caching). The iframe sandbox and CSP are relaxed only for content I control.
- Cost: under $1 a year for the domain, plus the free tiers of Google Sites and Cloudflare. The real cost was time — months of deliberate work under hard constraints.
Observed: Most of the complexity comes from two constraints: a locked CMS (no access to head tags or page structure, so everything is injected from outside) and a PSI score of 99 under a heavy animated background (hence the deferred hydration and cron-maintained visual state). Hypothesis: Astro or Next.js would remove much of that work, since server rendering and selective hydration are defaults there. Untested.
3. Why Clicks Are the Wrong Scoreboard
Observed (as of October 17, 2026): Cloudflare counted 5.17k visits in the last 30 days. Search Console recorded 20 clicks in the 28 days from September 17 to October 14. Google clicks are well under 1% of the activity.
Clicks and CTR were built for a human scanning ten blue links. More and more readers are machines that never click, and humans arriving via AI answers behave differently. So this experiment asks a different question: can machines parse this page? I measure that with things you can check yourself: what a bot receives with ?debug=bot, what Search Console renders, and whether the page gets indexed. Citation is the next scoreboard, and nobody has a tool for it yet.
Limit: those visits include my own testing and automation. The gap shows click metrics miss most activity, not that bots are the majority. Site size only scales the counts; the measurement is the same on any site.
4. The Limits
- Content quality still matters. Machine readability solves ingestion and token limits. Traditional SEO still applies.
- Fundamentals decide the outcome. Helpful content and user experience are what drive crawl demand. The edge cannot fake them.
- Payloads are hand-built per page. Each page needs its own KV entry plus a parity check. The cron AI Worker only maintains visual state (LCP image URL, background color); it does not write payloads. Automatic generation is the goal of the open-source build (see What Comes Next).
- Hypothesis: the edge code scales, since it runs per request, and generated payloads would extend it to many similar pages.
- Parity is a standing obligation. The ghost version must keep the same text content as the human version. If the two drift apart, it stops being dynamic rendering and becomes cloaking. Because the ghost HTML is a separate, hand-maintained copy, I run a text-parity check against the rendered page before each KV write (outside the Worker, which does not check at request time). You can compare it yourself: open the page normally, then with
?debug=bot, and diff the visible text. Expect two known differences: live telemetry numbers exist only in the human layer (the ghost copy shows placeholders), and the ghost copy carries short bracketed notes where the human layer renders interactive components. - Lighthouse/PSI is special-cased. Runs identified by User-Agent skip the script wake-up and the heavy-background upgrade, so lab scores describe that variant. Real-user (field) data is the check that matters.
- Hypothesis: the risk is contained and reversible. Remove the Worker and purge the cache. I'd be wrong if the origin still shows edge-injected changes after rollback.
5. What This Contributes
Everything below runs in production on this page and can be checked with the debug lanes and the validator:
- Iframe unboxing at the edge: the Google Sites embed is rewritten into inline
srcdocHTML, so its content is part of the document instead of hidden behind a sandboxed iframe. - Lane-based delivery: one URL, different packaging for humans, search crawlers and AI agents, with the text intended to stay the same and a query-parameter debug flag for each bot lane.
- KV-backed ghost payloads: per-path structured HTML (H1→H3 plus a JSON-LD @graph) served from edge storage, with a decoupled cron worker maintaining visual state so no AI runs at request time.
- Interaction-triggered hydration: native scripts are deferred until real interaction to keep the main thread free.
- Verification surfaces: a validator terminal,
?debug=bot,?debug=googlebotand a documented parity obligation, so each claim can be checked instead of trusted.
Architecturally, this is a strangler-fig-style approach: an edge layer in front of an untouched origin that upgrades pages one at a time, while unmigrated pages pass through as before. Unlike the classic pattern, the origin is never retired. It stays the source of truth. That is also why hand-written payloads are acceptable at this stage: each page can be migrated independently.
I am not aware of a public implementation that combines these for a locked CMS, though I have not done an exhaustive survey. It required distributed-systems work: an edge Worker, a decoupled cron worker, and asynchronous KV state.
6. What Comes Next: Open-Source, CMS-Agnostic Agent Readability
The real problem is bigger than Google Sites. Some crawlers still struggle with JavaScript. Retrieval pipelines differ. New agents keep appearing. You cannot chase every query. What you can engineer is how easy the page is to ingest cleanly.
Next step is to turn this from a single-site, hand-maintained prototype into an open-source, CMS-agnostic tool. The goal is simple: let people focus on useful content while the edge handles the machine-readable layer. No release date yet — still looking for the resources to build it properly.
The Google Sites deployment is the stress test: the approach working from outside a locked CMS. Hypothesis: the production target is EmDash, a full-stack TypeScript CMS built on Astro and Cloudflare Workers. There the edge can be the origin, so no mid-flight interception or iframe unboxing is needed, and humans and bots can receive the same structured HTML, which removes the parity risk. EmDash is in beta preview, so this is a direction to test, not a proven result.
What needs to exist:
- Ghost-payload generator: builds the structured, parity-checked bot copy from the rendered page (no more hand-written KV entries).
- Parity checker: diffs human and bot text and blocks the write when they drift.
- Crawler behavior matrix: a public, log-based record of how different agents actually behave.
- CMS adapters: validation on at least two platforms beyond Google Sites.
Proposed success measures: parity pass rate, tokens per page before and after, and a citation-test protocol with a larger prompt set across several engines, so the hypothesis that fewer tokens means more citation opportunity is tested rather than assumed. If you want to support or sponsor it, get in touch.
“Judge me by the constraints I can overcome, not just by the platforms I've already mastered.”
In this world, it isn't the big that beat the small, but the fast that beat the slow.
Get Closer to The Edge!
最 前 線